
If you’ve ever opened Claude, Lovable, or any other AI tool and seen a message saying you’ve reached your usage limit before lunch, this article is for you. If you’ve ever blamed yourself for “writing a bad prompt” when the AI gave you a mediocre answer, this article is also for you. And if you’ve ever wondered why some people can build entire products with AI in a week while you struggle to get through a single afternoon of work without hitting a limit warning message, then please, read on.
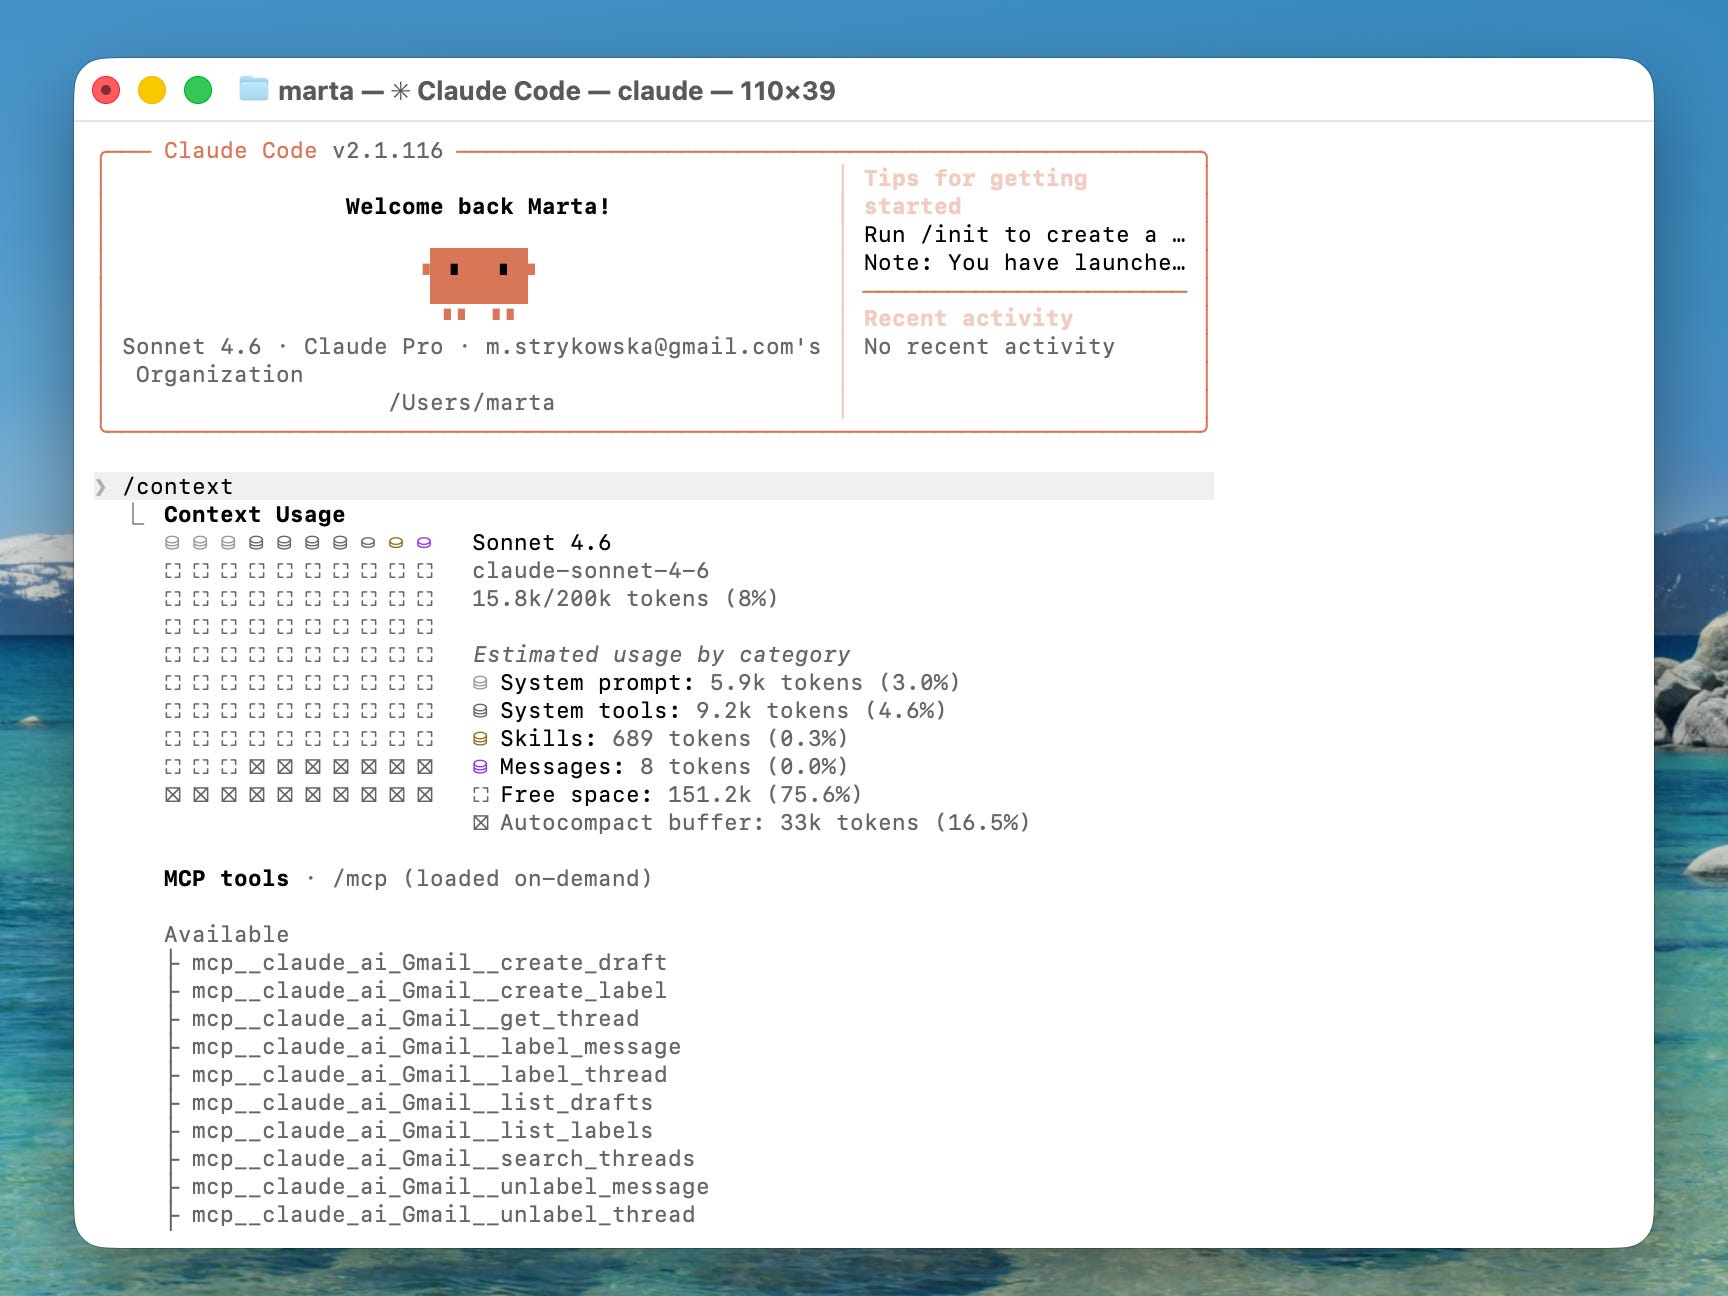
I want to talk about something that almost nobody is talking about, and it’s called context hygiene, i.e. what habits we need to practice to manage the context window properly.
What’s actually happening when you talk to LLM
I’m going to be honest with you, I always thought the context window worked like a storage tank filling up, so if you’d be at 99%, it would be almost over. It’t NOT like that.
Context window is the working memory of the AI within a single chat / conversation. When you overuse it, you don’t run out of tokens forever, you just need to start a new conversation, or compact the existing one, or apply some better habits to the way you work. The tokens are not gone, but you’ve simply hit the working memory limit of one chat.
Every single time you send a message to Claude or any other large language model, the model rereads every single message in your conversation from the beginning. Your very first message in the chat has a much lower cost/benefit ratio than by the time you reach message 30.
Usage limit is not the same as context window
Claude doesn’t sell credits the way some other AI tools do. Instead, your conversations across all interfaces are timed (“usage limit”), and your access is rationed on a five-hour rolling window in the Pro plan, with higher limits in Max. There’s also a weekly cap that runs simultaneously, refreshing seven days from when you started. When you hit one of these, you wait for the reset.
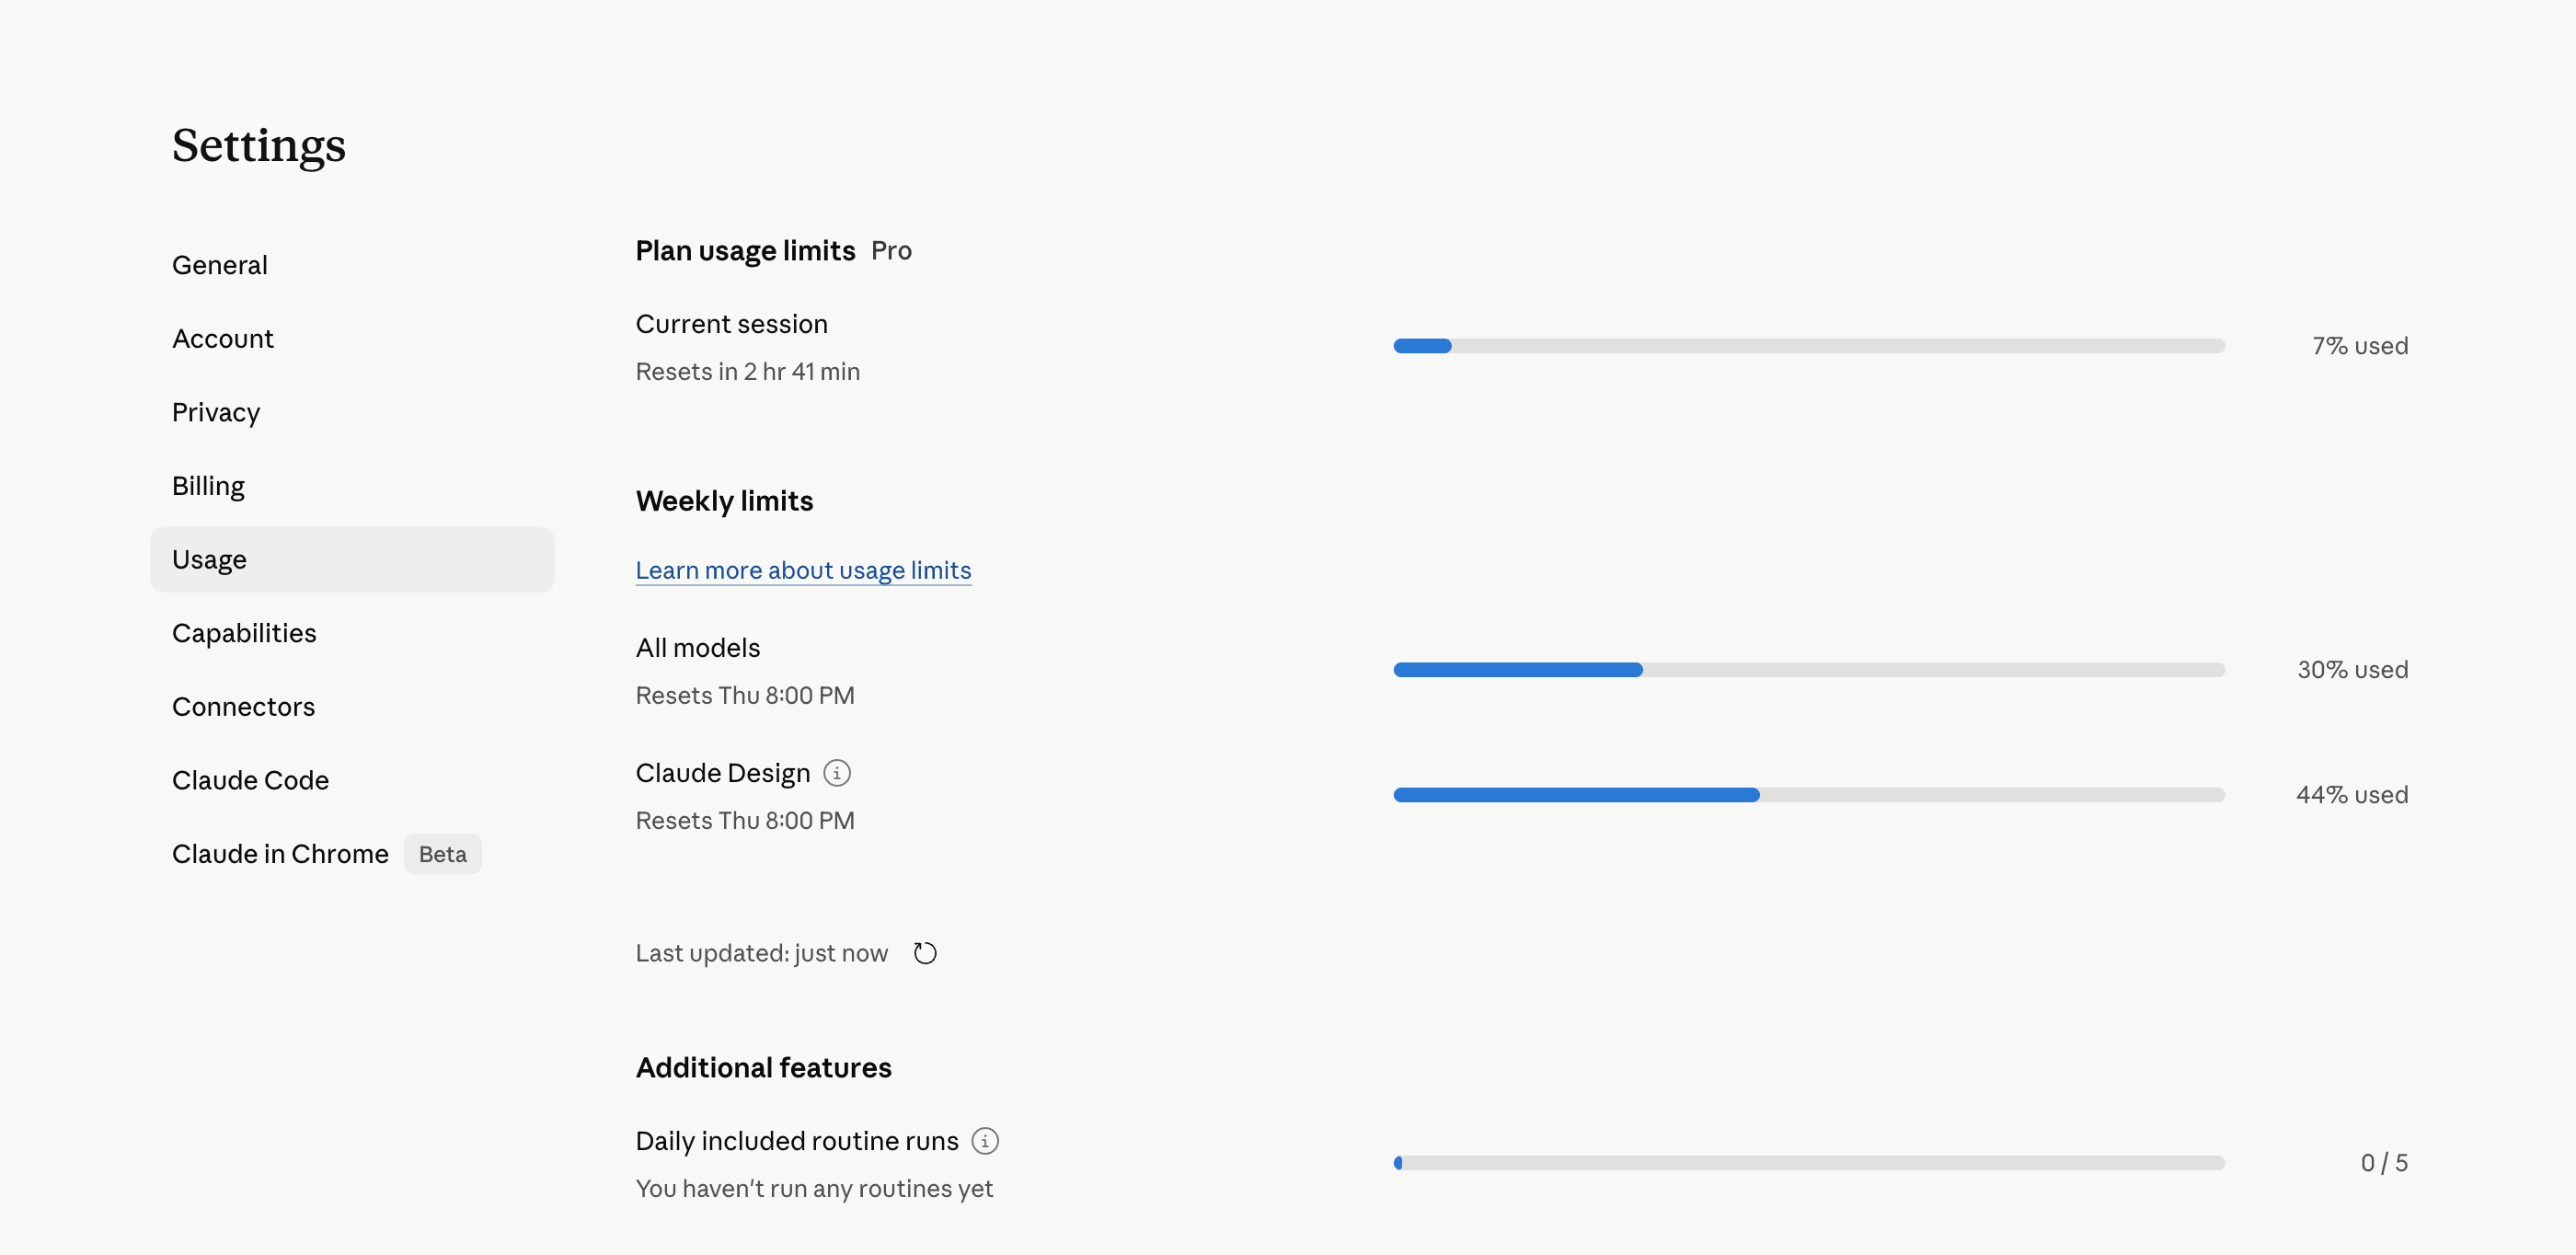
The context window is something completely different. It’s the maximum amount of content the model can hold in working memory during a single conversation, and for Claude that’s 200K tokens.
Context bloat, what is it?
Long conversations get expensive fast, and they get worse over time. Once you reach around 80% of the context window, which is roughly 150K tokens out of the 200K maximum that Claude offers, the model starts to bloat. It remembers the most recent parts of your conversation but begins forgetting the beginning. It hallucinates more and it loses track of instructions you gave it earlier, which means the work that AI produces during that bloated window often needs to be redone or corrected, which costs you yet more tokens to fix.
Your daily and weekly usage limits get reached faster, which means you wait longer for resets and in general, context bloat gets you less value for money.
So context hygiene is, at its core, about staying away from that context bloat zone, working in a focused way that gives the AI exactly what it needs and nothing more, and protecting both your usage limits and your output quality at the same time. It’s a discipline, and it’s a skill, and once you start practicing it, the difference is remarkable.
Two different set-ups with Claude, two different usage patterns
I want to write about the recent experiment I run with two projects set up in a different way with Claude and Claude Code and how much context window it cost me.
The first project was a fairly complex client deliverable, so I wanted Claude to assist me in building, not building the entire thing itself. Five different APIs, multiple components, custom pages, and an AI agent layer for delivering insights. I worked on it for about two weeks of focused effort, and across those ten working days, I never came close to hitting a usage limit. I ran two compress commands across the entire build, and at the end my highest context usage chat was at around 40%.
How did I do it? I used Claude through the chat interface, not through Claude Code or any IDE plugin. I asked focused questions, I copied the answers into my own code editor, and I executed everything manually. Every time I started working on a new feature, a new page, or a new API connection, I opened a new chat. To keep memory across those chats, I created a project space with shared instructions and a few markdown files: a PRD, a brief, brand guidelines. The chats lived inside this project, but each one had a tight, specific scope.
Was this slow? Oh, yes!
Was I doing more manual work than I had to? Absolutely!
But I was also fully in the loop.
I understood every line of code that ended up in my project. If a client called out a bug in the meeting, I could open the file and know exactly what was going on. I knew the work which I was paid to do.
The second project was different, because I wanted to run it in an agentic way, not via chats. I started in Claude Design, imported it into Claude Code, and let it build the entire thing for me. I had a PRD, .md files for my agents and I told Claude what I wanted. I was on the sidelines rather than on the field, because my only role was to approve things.
And by my second day of working on this project, having already run two compress commands, my top context window was at 80%. We weren’t even halfway through the week.
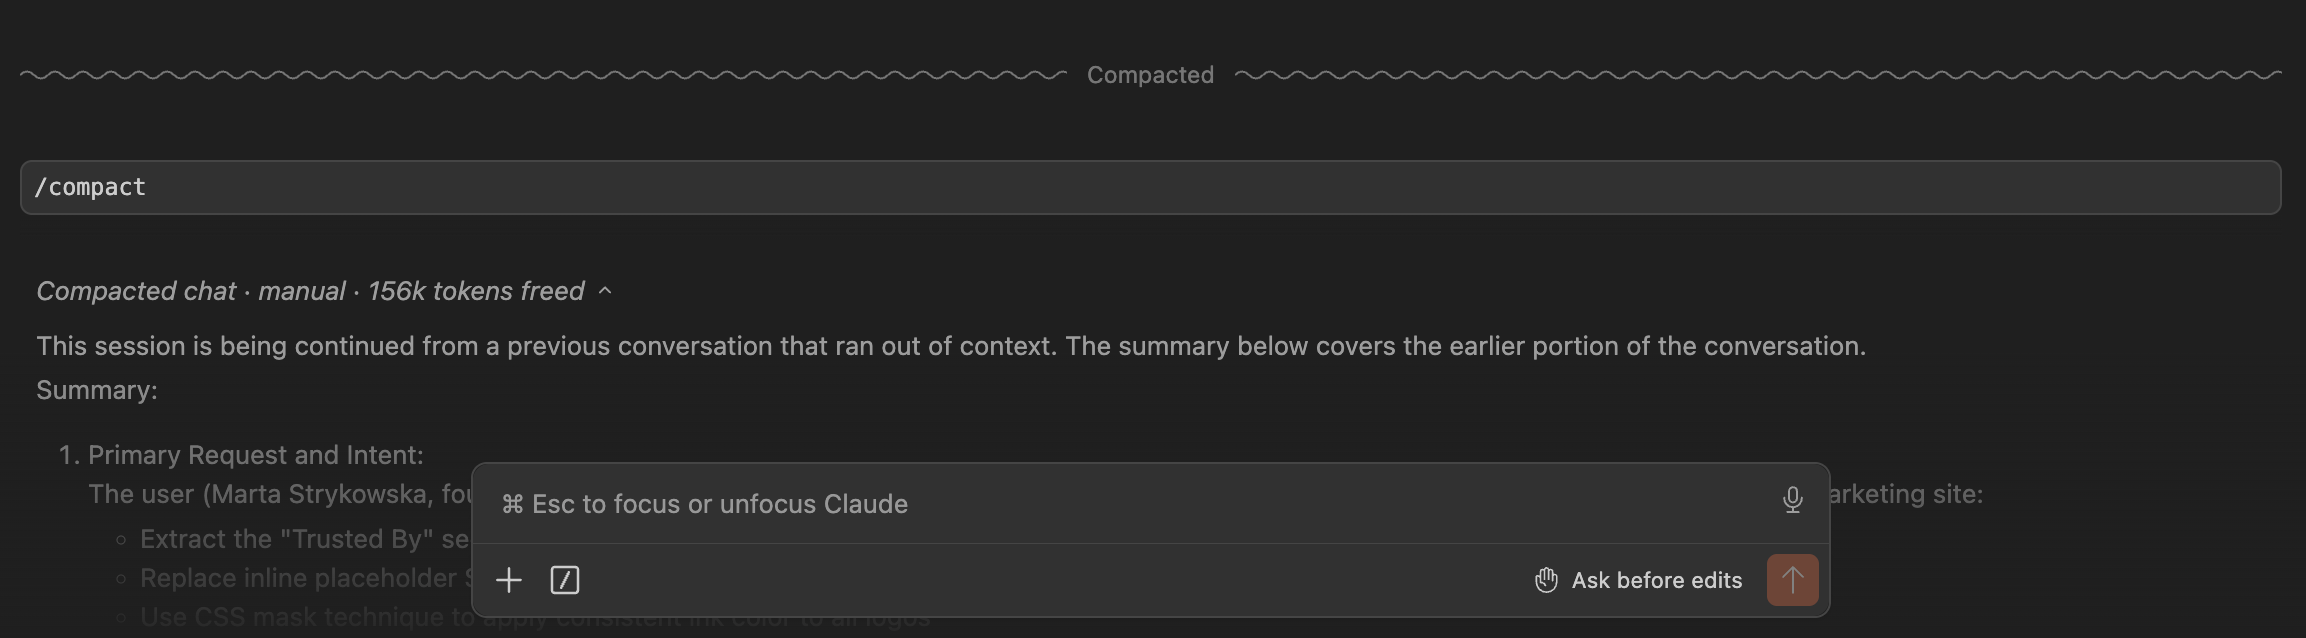
Now to be fair, this isn’t a clean comparison. One project used chat, one used agents. However, when you give Claude full autonomy, you save your own time but you seriously burn through credits. When you stay in the loop, you spend more of your own effort but the AI’s context stays clean and focused. It’s you who becomes the context window and the tokens, in a way. You hold the project memory in your own head, and the AI only ever has to know about the small slice of work it’s currently doing.
My key learning: agentic isn’t for everybody
Yes, vibe coding is amazing and it enables everybody to build things they’d need developers previously to build. BUT. Domain knowledge, “expertise” as we call it, and the confidence in doing or the sense of knowing where to look for when we have our own experience, is the best context we can have. And this is something most of the non-tech people don’t have at this point.
I wouldn’t recommend non-tech people to unleash their agents and have everything build for them, whilst they only approve things without good judgement. Agentic is powerful, but only if you really, really know what needs to be done and how. In that way you provide very clear criteria of good and bad, you have some visual of how the end result should look like, and as a result - you create discipline for managing the context window.
I would recommend using vibe coding apps like Lovable (single agent), where us as users are still very much involved in the building process and less damage can be done. Full agentic systems should be in the hands of people who know their sh*t, and have been doing this for some time.
If I now could redo my project no.1, I would implement it in an agentic way via Claude Code, but only because I now have a good understanding of how it should look like in the end. If I did this without this knowledge, I would probably have lots of rework on my plate right now.
The most painful surprise: I was burning tokens on things I wasn’t even using
Now I want to share what was honestly the biggest sucker punch of this whole learning process for me, because I want you to avoid making the same mistake.
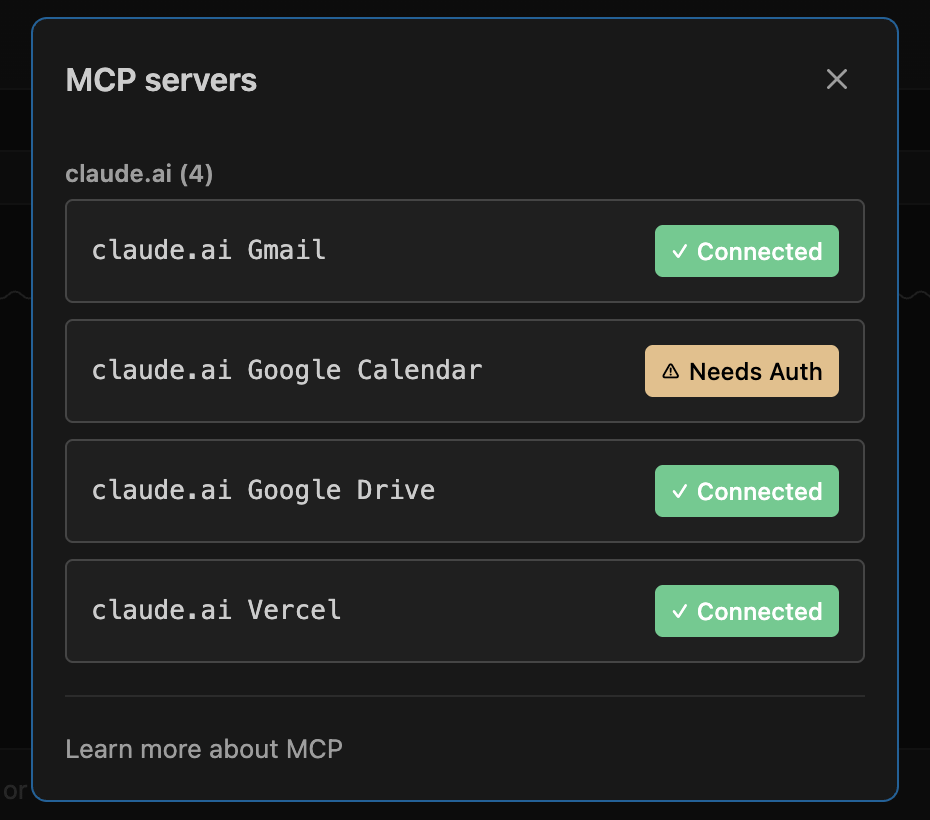
When I finally started looking properly at where my tokens were going, I discovered that 19% of my context window was being eaten up by MCP tools and connectors that I had enabled but wasn’t actually using: Notion, Gmail, Granola, Airtable, the whole list. When I started in Claude, I enthusiastically turned them all on, with the thinking of “well, I might need them eventually.” Turns out, even when you don’t actively call those tools in a conversation, they still load every single time you start a project.
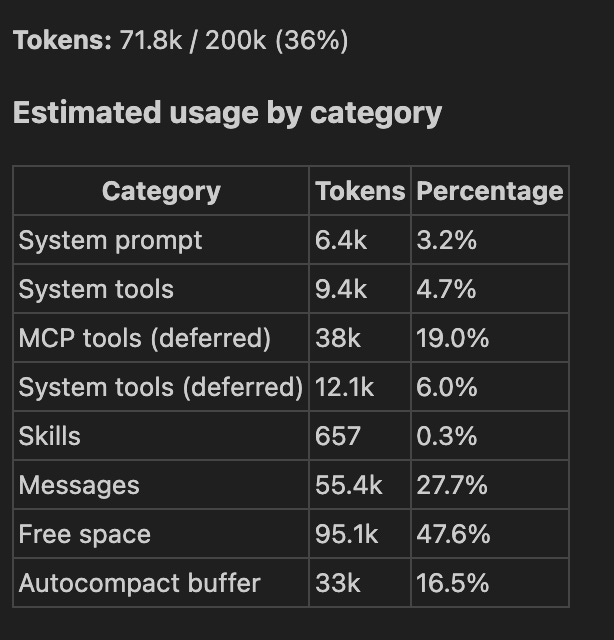
I wasted 38K tokens before I even typed a single character into a project!!!
If you want to see this for yourself, type /context in Claude Code and you’ll get a full breakdown of where your tokens are going within a conversation. Type /usage and you’ll see how much of your subscription allowance you’ve burned through. I now run /context with about the same regularity I commit to Git. It’s become part of my workflow, and honestly it should be part of yours too.
The lesson here is: turn on only what you actively use, and turn off the rest. It feels like such a small detail, but it’s an instant cleanup of your context, and you’ll feel the difference immediately. Run command /mcp to understand, which servers are running in your background, so you can also disconnect them if not needed:
Practical context hygiene tips for you
Now for the practical part. Here are the habits that have genuinely made a difference for me, in roughly the order of how much they’ve helped.
Stop using PDFs when you don’t have to. This was a revelation for me. PDFs are designed for humans, who like layout and formatting and visual structure, but models need text only. To read a PDF, the model first has to process all the structural information, the headers, footers, columns, fonts, before it can even start understanding the content. I tested this myself. The same prompt with 3 small PDFs cost me 8K tokens. With the same content as markdown files, it dropped to 5K and with just text pasted into the chat it was close to 3K. That’s a savings of more than half, on three small documents. Imagine the difference on 50 PDFs uploaded.
Use one chat per task or feature, not one chat for an entire project. The longer a chat gets, the more forgetful and unreliable the model becomes. When I’m building, I open a new chat for each new feature, each new page, each new API connection. If I notice the AI is going off the rails, I just start fresh, sometimes with a different model to see if that helps.
Don’t use the newest models by default. Think about it like buying wine. You don’t need a fifty-euro bottle for a regular Wednesday dinner, right? Learning to match the model to the task is a skill in itself, and it pays off enormously over time.
Use different tools for different jobs. Extension of point 3, but I also learned it the hard way. If you need real research from the web, Perplexity might do that cheaper than asking Claude to do it via the browser extension.
Don’t dump your entire codebase or every reference document into one place like Claude.md file at the start of a project. This is an official best practice from Claude, but logically it makes no sense. If you hire someone to be your office barista on day one, you don’t hand them every single document the company has available. The same applies to AI agents: smaller, focused context files per agent or per task make far better use of tokens than one giant dump of everything.
Run /context regularly and learn what’s eating your tokens. This is how you actually get better over time. You start to understand which kinds of tasks are expensive and which are cheap, and you adjust your workflow accordingly.
Why this matters beyond your own subscription
I want to close on something bigger, because I think this conversation usually stays at the individual productivity level, and it shouldn’t.
If you manage AI in any kind of organisation, even a small one, this stuff has enormous implications. Imagine a company of 50 people, each one of them quietly burning through tokens by leaving every connector enabled, dumping PDFs into chats, and running enormous unfocused conversations all day long. Multiply that across an entire workforce. The cost is staggering, and the output quality is worse than it should be on top of it.
Context hygiene needs to become part of how we train people to use AI at work. Not just “write better prompts,” not “remember to avoid writing please” (true advice I heard at the training) or whatever surface-level advice gets passed around in trainings. We need actual literacy around how these models work, where the tokens go, and how to be efficient with them. I think this will start showing up in job descriptions and interview questions soon enough, and the people who understand it early will have a real edge.
We often blame ourselves for getting bad AI output. We assume we wrote the wrong prompt, or chose the wrong words, or didn’t give enough detail. Sometimes that’s true. But often the real problem is upstream of the prompt entirely. The context was too bloated, the chat was too long, the model was already drowning before our prompt even arrived. Knowing this changes how you diagnose problems, and that alone is worth the time it takes to learn.
This topic keeps on evolving, and I’m still not entirely convinced if I’m using AI in the most sustainable way, but at least it’s good practice to start measuring what you can and introduce good context hygiene habits to optimise your AI set up for the long run.